dsh-skill-eval
carlslin/dsh-skill-eval
用真实执行遥测(加载成败、后续工具报错、用户纠正、被忽略与成本)给每个技能打 0-100 分并附 95% 置信区间,再把证据转成 agent 可直接执行的修复建议。
安装
dsh plugin --profile web add github:carlslin/dsh-skill-evalREADME
dsh-skill-eval


Records what happens after a skill is loaded, scores every skill 0–100, and
turns the evidence into fixes the agent can act on. It is a DeepSeek Harness
(DSH) plugin: telemetry, the scoring board and the agent-facing
skill_eval_report tool ship together.
Most skill-quality tooling checks the skill file. This plugin checks the execution: did the load succeed, did the tools that followed fail, did the user push back, was the skill ignored, did it collide with a sibling skill, what did it cost. Those signals only exist inside a running harness — which is why this is a DSH plugin rather than a CLI.
中文速览 · TL;DR for Chinese readers
- 在每次
skill加载后收集执行遥测:加载成败、后续工具报错、用户是否推翻、是否被忽略、碰撞与成本。 - 每个技能 0–100 分(A≥90 / B≥80 / C≥70 / D≥60 / F<60),带 95% bootstrap 区间;区间重叠时排名标为不显著。
- 入口只有三个:回合下方结果条、侧边栏「技能评测」面板、设置 → 插件 →
dsh-skill-eval的配置页。 - 建议靠规则生成,每条都带触发数字和可执行的修复;中文界面下标题与修复为中文。
- 完整中文文档:README.zh.md;入口清单:docs/ENTRYPOINTS.md。
What you get
- a result strip in the conversation — under every completed turn that loaded a skill, a one-line card shows the skill scores, this turn's call/error counts and an expandable list of fixes (zero tokens, no popup). The old popup is opt-in (
window.__SEV_ENABLE_POPUP__ = true). skill_eval_reporttool — the agent reads its own telemetry instead of guessing/skill-eval [skill]command — same report in the composer/skill-eval/board/<version>— HTML board with grades, dimension bars and top fixes- append-only JSONL telemetry in
$DSH_HOME/skill-eval/$DSH_PROFILE/events.jsonl(bounded to 8 MB: the oldest records are trimmed once it fills, with theeditaudit ledger kept, so a long-lived profile cannot grow without limit)
Screenshots
| Skills board | MCP tab | Scoring settings |
|---|---|---|
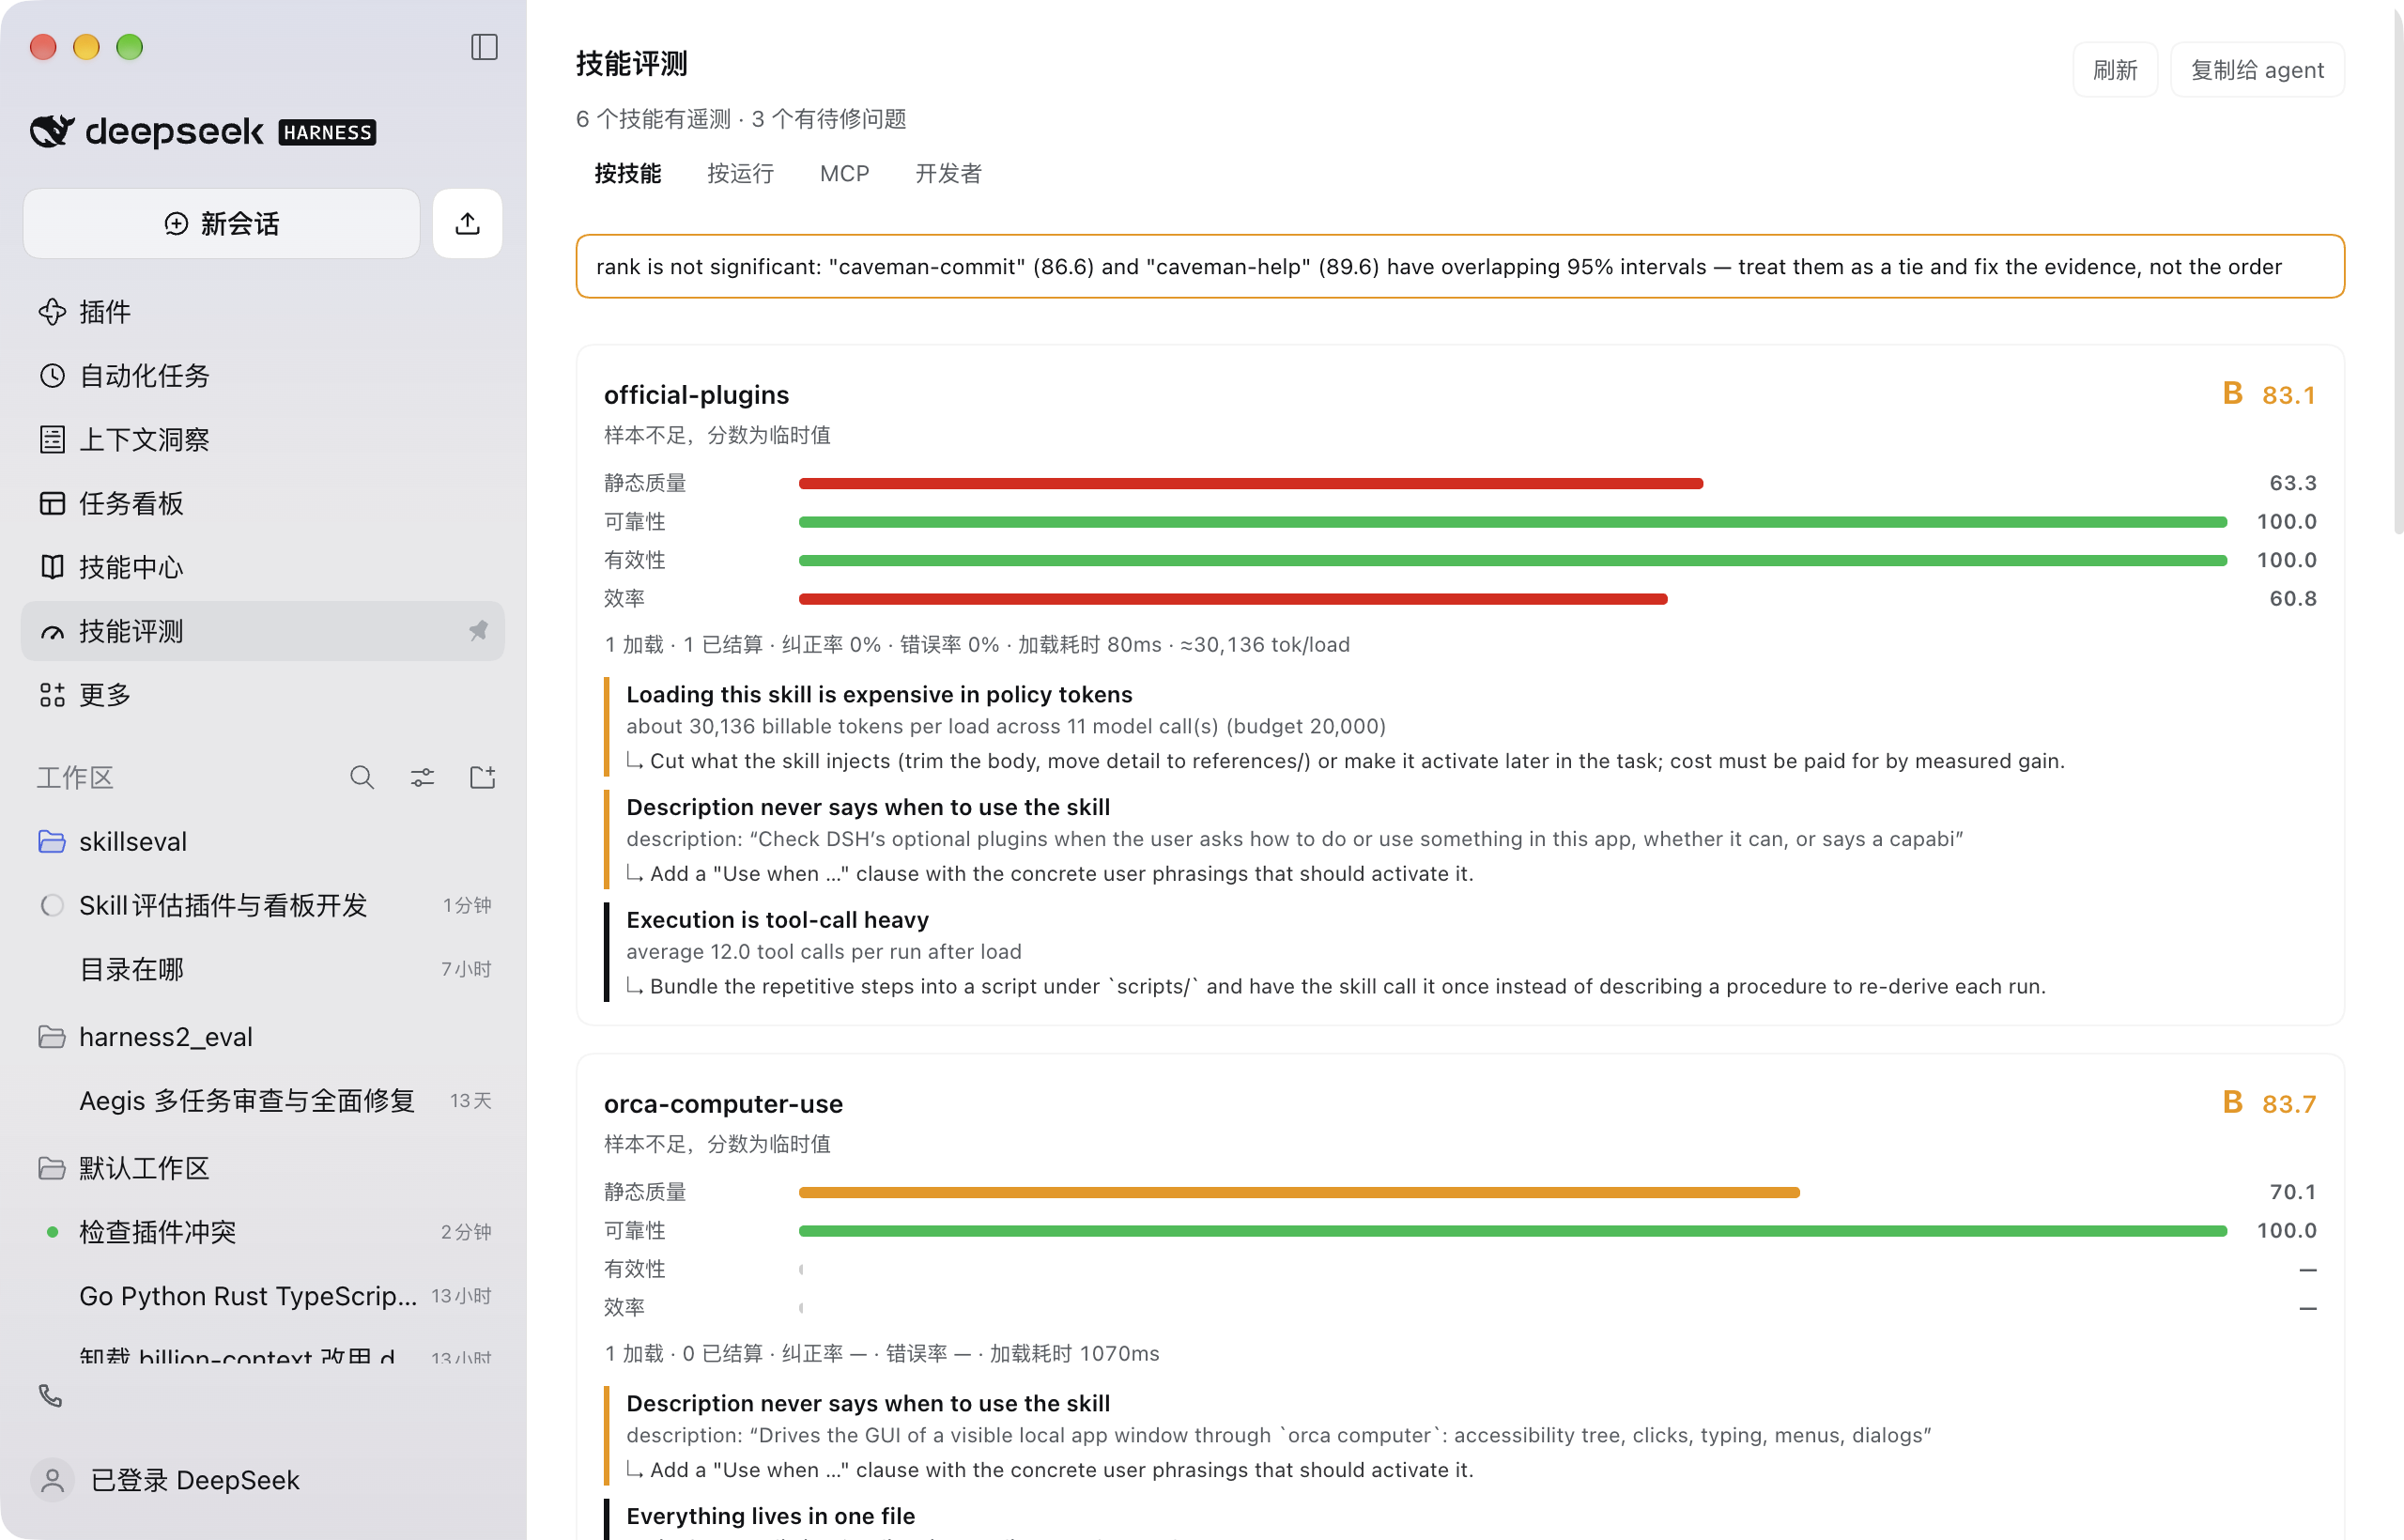 | 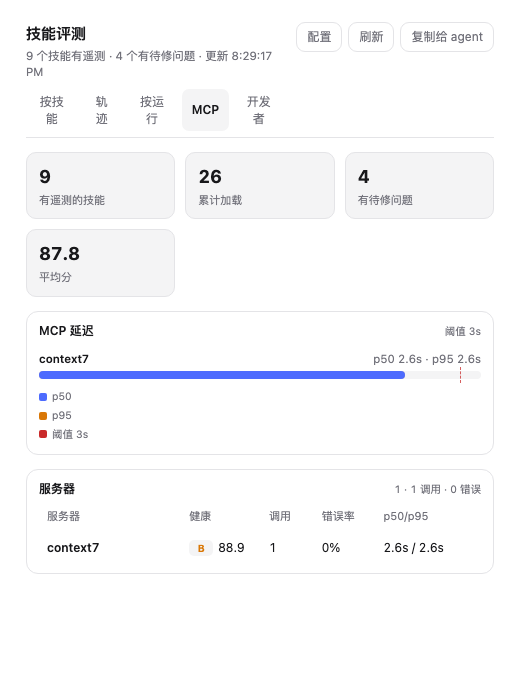 | 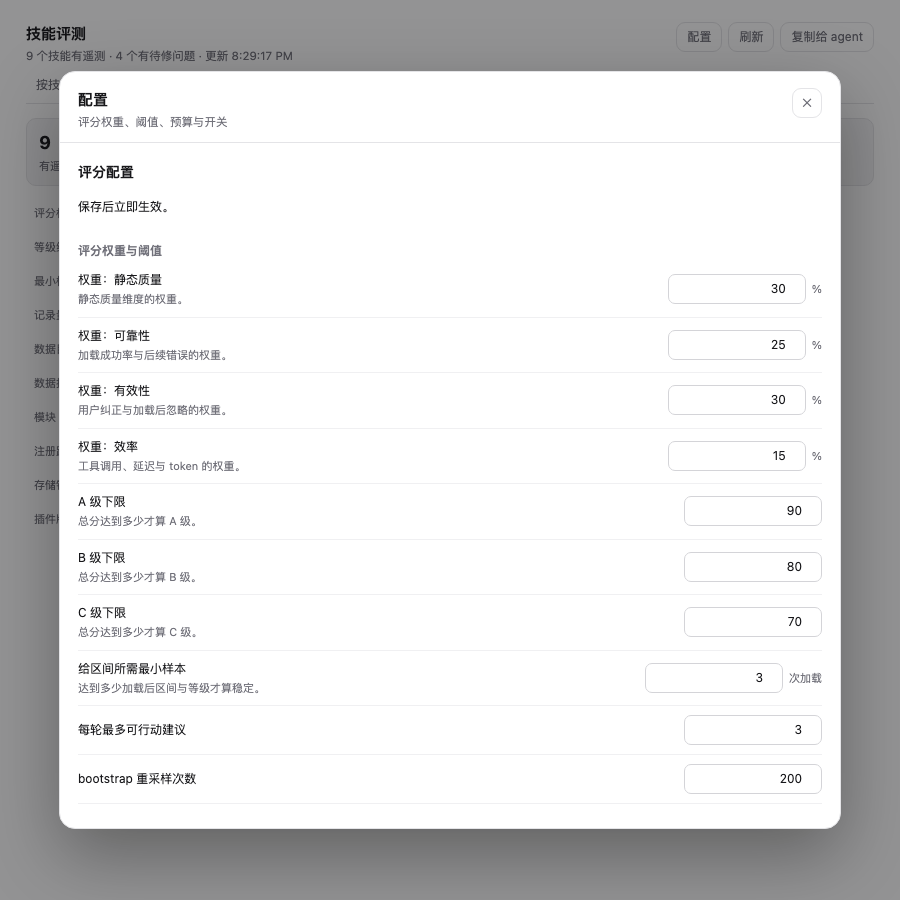 |
More real-window screenshots and the per-screen notes: docs/UI-REVIEW.md.
Scoring in one look
| dimension | weight | signal |
|---|---|---|
| static | 0.30 | description, trigger cues, progressive disclosure, size, examples |
| reliability | 0.25 | load success × post-load tool error rate |
| effectiveness | 0.30 | user corrections, ignored loads, sibling collisions |
| efficiency | 0.15 | tool calls per run, load latency |
Grades: A ≥ 90, B ≥ 80, C ≥ 70, D ≥ 60, F < 60. Every score carries a
95% bootstrap confidence interval; overlapping intervals are reported as a
non-significant rank. Dimensions without evidence are dropped and their weight
redistributed. Full rubric, record schema and formulas: docs/DETAIL.md.
Advice is never generic. Each item carries the number that triggered it and a concrete edit:
🛑 [critical] The user rejects the result right after the skill runs (effectiveness)
   evidence: 67% of runs were followed by a correcting message (e.g. "不对,页眉没删掉")
   fix: The body likely ignores stated constraints. Tighten the output contract and
        the "do not" list; add a short self-check the model must run before answering.
Entry points
Everyday use is three places only:
| Goal | Where |
|---|---|
| See this turn's result | the result strip under a completed turn (score, calls/errors, next fix, edit history) |
| Open the board | the Skill eval panel icon in the sidebar (main panel, same seat as the context plugin) |
| Change scoring | Settings → Plugins → the dsh-skill-eval bundle page → Configure |
Web board: /skill-eval/board/<version> · web settings: …/config · JSON:
…/data/<version>. Slash commands, agent tools, terminal checks and debug
switches: docs/ENTRYPOINTS.md.
dsh-skill-eval-doctor   # packaging pre-flight (release gate with --release)
dsh-skill-eval-accept   # generation & data contract (17 checks)
dsh-skill-eval-verify   # product surfaces (7 checks + 2 manual, after a reload)
Install
Requirements: DeepSeek Harness with plugin bundles (the package declares
dsh.engines.dsh >= 0.2.0) and Node.js ≥ 20 for the CLI helpers.
From npm:
dsh plugin --profile desktop add dsh-skill-eval
From GitHub source. A clone contains src/ only. index.js, lib/, scripts/
and client.js are build output, and the host loads those files. Pack the
compiled tree and install the tarball. Do not point dsh plugin add or
plugin_manager → install_bundle at the git checkout.
git clone https://github.com/carlslin/dsh-skill-eval.git
cd dsh-skill-eval
npm install          # prepare compiles the runtime files
npm pack             # tarball of those files, not the git tree
dsh plugin --profile desktop add "$PWD"/dsh-skill-eval-*.tgz
From a packed release tarball (what a published build ships):
dsh plugin --profile desktop add "$PWD/dist/dsh-skill-eval-<version>.tgz"
The npm package and the release tarball are prebuilt. A git checkout is not.
Editing src/client/*.ts requires npm run build:client, which uses the
typescript devDependency to strip types and write client.js. After install,
refresh the GUI: the board is the Skill eval panel icon in the sidebar,
settings live under Settings → Plugins → dsh-skill-eval.
Use
- Result strip under every completed turn: score chip, calls/errors, next fix and edit history (zero tokens).
- Board: skills / steps / runs / MCP / dev tabs with next steps and evidence validity, plus SVG charts (score distribution, skill trend sparkline, evidence coverage, MCP p50/p95, session activity). The steps tab scores every loop step and compares recent turns. Each skill card has a Copy issues button next to 查看轨迹 that copies the card's current issues, score, dimensions and evidence as one self-contained Markdown repair task; each advice row keeps its own copy button.
- Agent: ask "how did
pdf-toolsperform?" — the agent callsskill_eval_report; before editing a skill it is told to callskill_eval_reviewfirst. - Slash commands:
/skill-eval(summary),/skill-eval <skill>,loop [all],validity,history,impact,mcp,runs,turns,dev,config,accept. - Read-only Inspect: provider
skill-eval, methodssummary|skill|mcp|runs|edits|standard. - To improve a skill: act only on
critical/warningitems, apply thefixlines, then re-read after a few more loads.
Config
The form lives in the bundle page; the same values can be seeded in config or
settings.json. The essentials:
enabled: true
windowToolCalls: 12 # tool calls that count as evidence for one load (live)
windowTtlMs: 1800000 # how long an open window waits for follow-up work
minSamples: 3 # loads before a score stops being provisional
weights: { static: 30, reliability: 25, effectiveness: 30, efficiency: 15 }
thresholds: { excellent: 90, good: 80, pass: 70 }
tokenBudgetPerLoad: 20000 # billable tokens per load before efficiency/advice react
adviceNoiseFloor: true # advice must clear its 95% interval to stay critical
redactCorrections: false # true = store "[redacted N chars]" instead of user text
turnReports: true # one board per settled turn under reports/turns/
turnReportsKeep: 50 # per-turn boards to keep
reportOnTurnEnd: true # write reports/latest.md + latest.json after each turn
# snapshots: { latest: true, turns: true, keep: 50 } # same trio as one object
promptHint: true # the one-line system-prompt hint; false = zero fixed cost
registerReviewTool: true # skill_eval_review: leakage critic + audit ledger
Full key list (31 settings incl. pruning, edit budget, cache weight, MCP tool
thresholds, dashboard path and the snapshots trio):
docs/DETAIL.md.
DSH_SKILL_EVAL_DIR overrides the data directory; $DSH_HOME/skill-eval/$DSH_PROFILE
is the default. Data/settings JSON stays under the canonical /skill-eval
base and is mirrored under a custom dashboardPath, so a moved board keeps
working after a hot reload.
Release
See docs/RELEASE.md for the checklist, packing commands and
the clean-profile smoke test. npm run release:check runs the doctor gate, the
test suite and the live acceptance; node scripts/doctor.mjs --release verifies
the matching dist/ artifact.
Build
Editing src/client/*.ts requires rebuilding the single-file browser bundle:
npm run compile        # tsc → emitted index.js/lib/*.js/scripts/*.mjs + client.js
npm run build:client   # same emit; works when scripts/ is not already built
npm run typecheck      # strict tsc for host, client and test projects
npm run build          # format check → lint → compile → doctor → the test suite
npm run build:fast     # compile + doctor only
npm run build:pack     # full build + dist/dsh-skill-eval-<version>.tgz
npm run build:install  # pack + install into the desktop profile
scripts/build.mjs runs the same commands as the release checklist; add
--fix to format before checking, --install=<profile> for another profile.
Tests
npm test
npm test compiles first, then runs the suite against src/ (not a previous
lib/*.js). The suite command is
node --experimental-strip-types --test "test/**/*.test.ts"; the explicit
glob is required because Node 22/24 treat a bare directory argument as an entry
module. Scoring bands, static checks, correction detection,
window lifecycle (turn-end snapshot → correction → close), store round-trip with
a torn line, analyzer join, markdown/HTML rendering incl. escaping and bilingual
advice copy, host route registration under duplicate-route pressure, and the
client surfaces mounted in jsdom.
More docs
- docs/AUDIT.md — multi-layer audit: findings, fixes, residuals
- docs/CODE-REVIEW.md — code-hygiene review: dead code, duplication, cleanup
- docs/UI-REVIEW.md — real-window walkthrough with screenshots (
docs/ui/) - docs/ENTRYPOINTS.md — every entry point, including slash commands and debug switches
- docs/WORKFLOW.md — load → measure → score with intervals → advice → screen edits → re-measure
- docs/DETAIL.md — rubric, record schema, full configuration keys, why this exists
- docs/RRSI-NOTES.md — research notes and what we borrowed
- docs/COMPARISON.md — prior art and what each misses
- docs/DEV-RELOAD.md — hot-reload recipe and disposable-profile verification
- CHANGELOG.md — release history
Known limits
- Loads are recorded from
skilltool calls and user-typed/skill-nameinvocations; a skill the harness activates without either is invisible. - Effectiveness is inferred from the next user message, not from a task verdict.
- Advice evidence keeps measured ids/numbers in English even in the Chinese UI; evidence tables escape Markdown so skill names and user text cannot break the report layout.
- Telemetry is bounded to 8 MB (
events.jsonlrotates to its newest half, keeping theeditaudit ledger first). Step rows are the dominant growth in long sessions; per-skill trends keep the last 12 loads and runs keep the last 20 sessions. - Small samples never report strong significance: rate gates with fewer than 8 windows cap at
info, and prune advice requires at least 6 loads (the configuredpruneMinLoads, default 12) plus a bootstrap interval below the bar. - Privacy: user correction text is stored by default; set
redactCorrections: trueto keep only[redacted N chars]. Report/board reads reject cross-site fetch metadata.